Agent Mesh: My Thoughts on Multi-AI Collaborative Workflows
- EN
- ZH-CN
Table of Contents
AI coding assistants are everywhere now, from chat windows to CLI Agents. After using a bunch of them, my biggest takeaway is: no single Agent is the best at everything.
I mainly use Claude Code, Google Gemini CLI, and Moonshot Kimi Code day-to-day. At first I treated them as standalone tools, but soon realized that was a waste — each has distinct strengths, and if you let them collaborate and delegate tasks based on those strengths, the results are much better. I call this approach Agent Mesh.
#
Core Roles: My Observations and Real Experience
##
Claude Code: Planning and Execution
I mainly use Claude Code to create projects and refactor code. It can traverse files, run bash, fix compile errors, and continue with the next step. I’ve installed it on all my servers. Its weakness is hallucinations, especially when generating long documents or referencing large systems it hasn’t fully understood.
##
Gemini CLI: Large-Context Consumer and “Hallucination Checker”
Gemini’s biggest advantage is that 2-million-token context window. In practice, it really can swallow an entire repository or very long error logs (I’ve tested with logs of several hundred KB). Because it can hold the entire macro context in its head, it’s a natural auditor. When Claude Code produces a brilliant but potentially hallucinated code plan, you can call on Gemini for large-scale cross-file verification.
##
Kimi Code: Deep Reasoner and Data Miner (❓ Pending Evaluation)
Kimi Code takes a completely different path. Under the hood it runs K2.5’s “long thinking” model (k0), using explicit chain-of-thought (similar to OpenAI o1’s approach), plus an “Agentic Swarm” pattern that can theoretically spin up a swarm of sub-Agents for multi-hop document retrieval or grinding through deeply nested algorithmic problems. I do have a question mark here though: I use Claude and Gemini every day, so I have a solid feel for their capability boundaries, but how much better Kimi actually is at “data mining” and “deep reasoning” compared to the other two — honestly, I’m mostly going by its architectural claims and haven’t done rigorous head-to-head evaluations yet. So for now, its niche here is only a theoretical one.
#
What My Ideal Agent Mesh Looks Like
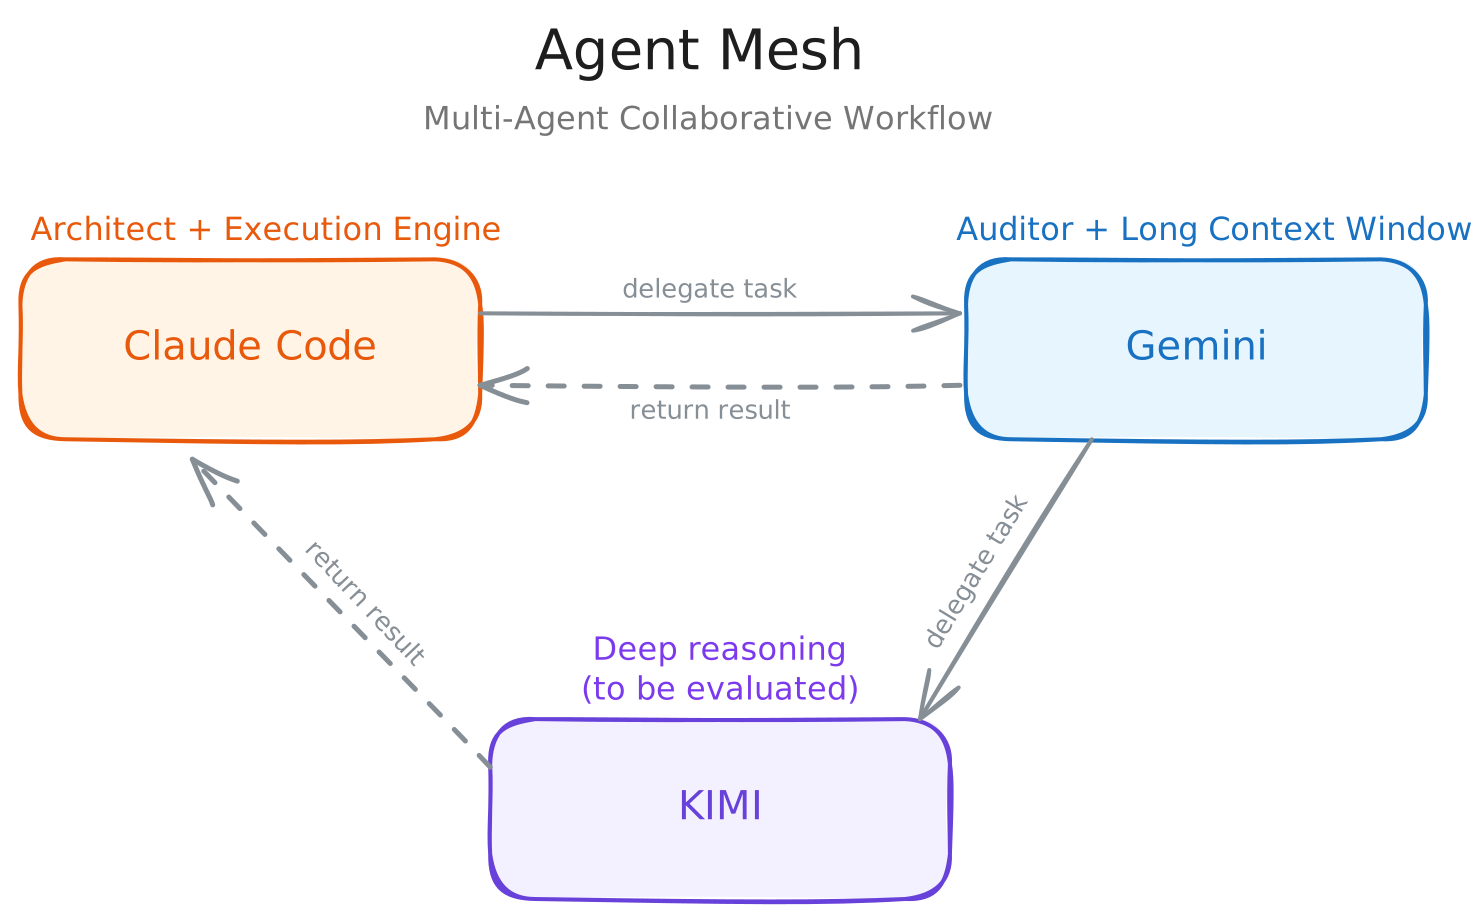
Most of the time, Claude Code is the workhorse — it writes the vast majority of the code. But when it hits a context ceiling, say I need to refactor a module but don’t know which parts of a 500K-line legacy codebase will be affected, I hand it off to Gemini — let it read the entire repo and report back the blast radius.
Conversely, after Claude executes a refactoring plan, I’ll have Gemini cross-reference it against the actual project files to catch hallucinations or broken dependencies. If Gemini encounters a particularly tough algorithmic problem during auditing, it can pass it to Kimi Code for extended reasoning.
After Kimi finishes thinking, it doesn’t touch files directly — it passes conclusions back to Claude Code for implementation. The whole flow is a loop: each does what it’s best at, and results flow between them.
#
The Hidden Factor: Agent Architecture vs. Base Model
When combining these Agents, I consider both the base model and the tool’s execution workflow.
For example, Anthropic’s Claude 3.5 Sonnet can be used in multiple environments:
- As a standard chat assistant in VS Code.
- As the driving engine inside Cursor IDE.
- Through open-source Agent frameworks like OpenHands / Open Code.
- Natively via the Claude Code CLI.
In the engineering workflows I’ve used, tools can feel different even when they use the same model. Claude Code’s file operations, command execution, and error recovery work together more smoothly for me.
#
Similar Explorations in the Community
After writing this up, I found that others in the community are working on similar ideas. Humanize is a Claude Code plugin that implements a workflow called RLCR (Ralph-Loop with Codex Review): Claude writes the code, Codex independently reviews it, and if issues are found, it gets kicked back for rework, looping until everything passes. The core idea is the same as Agent Mesh: let architecturally different AIs each do what they’re best at, iterating through a work-feedback loop instead of expecting one model to nail everything in a single shot.
#
Final Thoughts
Alongside assigning different roles to the same model, I also consider differences between models and Agent workflows. LLM-DNA is a research framework for analyzing evolutionary relationships and functional differences between language models, published in ICLR'26. It can help explore differences between models.
In my projects, Claude Code and Gemini CLI are the combination I find easiest to work with: Claude writes and executes code, while Gemini reviews changes in the context of the whole repository.